AMD Instinct MI350X GPU: Specs, CDNA 4 & AI Performance
What Is the AMD Instinct MI350X GPU?
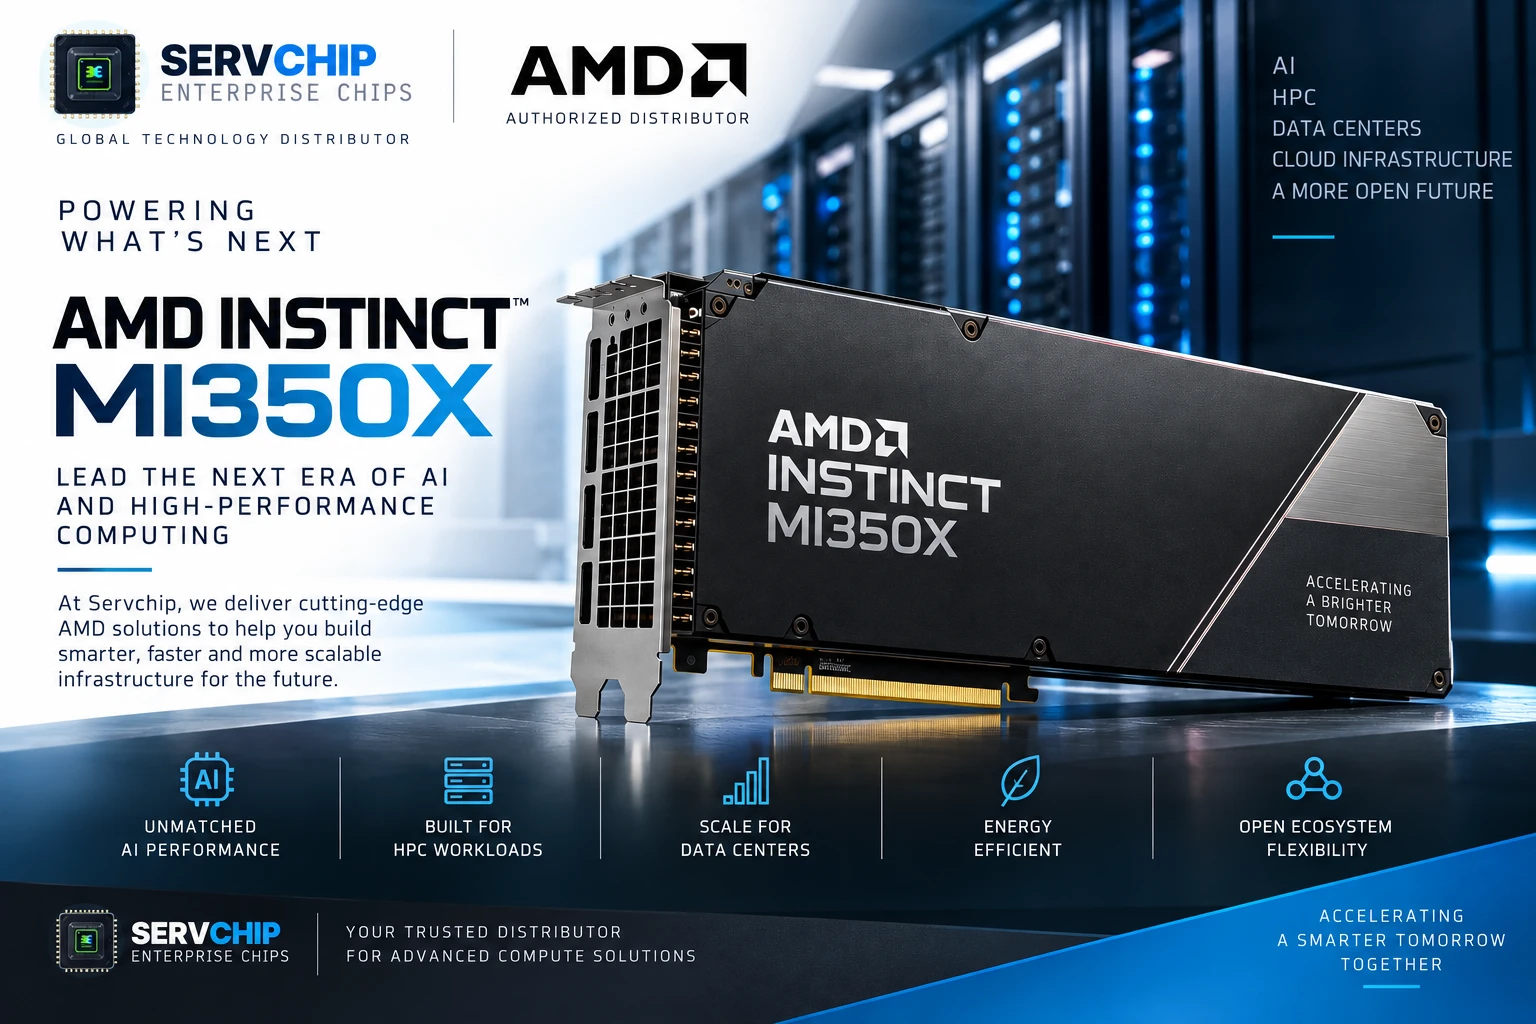
The AMD Instinct MI350X Accelerator is a data center graphics processing unit (GPU) built on the 4th-generation AMD CDNA 4 architecture, designed specifically to scale massive generative AI models and High-Performance Computing (HPC) workloads.
Equipped with a massive 288 GB of HBM3e memory, an 8 TB/s memory bandwidth, and native support for low-precision data types like MXFP4 and MXFP6, the MI350X delivers up to 9.2 PFLOPS of FP4 matrix compute.
Operating within a 1,000 W Thermal Design Power (TDP) air-cooled OAM form factor, it offers up to a 35x generational leap in inference performance over its predecessors, positioning it as a direct competitor to top-tier enterprise AI hardware available through leading hardware suppliers like Servchip.
Architectural Breakdown: What Makes CDNA 4 Different?
At the heart of the AMD Instinct MI350X lies the refined CDNA 4 architecture. Unlike consumer graphics cards optimized for real-time rendering, CDNA 4 strips away standard display pipelines and focuses entirely on parallel compute density, matrix operations, and high-speed data interconnects.
| Architecture Block | Design |
|---|---|
| Memory Stacks | 288 GB HBM3e (12-high stacks) — 8 TB/s ultra-high bandwidth |
| On-Die Cache | 256 MB Infinity Cache (L3) |
| Compute Dies | 8x Accelerator Complex Dies (XCDs) on TSMC 3nm — 256 Compute Units (CUs), 16,384 Stream Processors, 1,024 Matrix Cores with native FP4 / MXFP6 / FP8 support |
| I/O Dies | 2x I/O Dies (IODs) on TSMC 6nm — 4th-Gen Infinity Fabric Interconnect links and PCIe 5.0 x16 host interface |
Multi-Chiplet Design and 3nm Manufacturing
- Compute Dies (XCDs): 8 Accelerator Complex Dies manufactured on TSMC's advanced N3P (3 nm) process.
- I/O Dies (IODs): 2 I/O dies built on a 6 nm node, streamlined from the previous 4-die setup to optimize routing efficiency and power utilization.
- Transistor Count: A staggering 185 billion transistors packaged across a multi-chiplet substrate.
AMD continues its leadership in chiplet engineering by combining advanced TSMC manufacturing nodes to maximize compute density per watt. To explore similar enterprise chip architectures and accelerators, browse through our AMD Instinct lineup.
AMD Instinct MI350X Technical Specifications
| Feature / Specification | AMD Instinct MI350X |
|---|---|
| GPU Architecture | AMD CDNA 4 |
| Process Node | TSMC 3nm (Compute) / 6nm (I/O) |
| Transistor Count | 185 Billion |
| Compute Units (CUs) | 256 CUs |
| Stream Processors | 16,384 Cores |
| Matrix Cores | 1,024 Cores |
| Memory Capacity | 288 GB HBM3e |
| Memory Bandwidth | 8.0 TB/s |
| On-Die Cache | 256 MB Infinity Cache |
| Peak FP4 Compute | 9.2 PFLOPS |
| Peak FP8 Compute | 4.6 PFLOPS (Dense) / 9.2 PFLOPS (Sparse) |
| Form Factor & TDP | OCP Accelerator Module (OAM), 1,000 W Air-Cooled |
Key Performance Innovations for AI and High-Performance Computing
288 GB HBM3e Memory for Unmatched Context Windows
Memory capacity remains a massive bottleneck when serving Large Language Models (LLMs) with hundreds of billions of parameters. The MI350X solves this by mounting 288 GB of 12-high HBM3e memory.
This high memory density allows enterprise teams to fit 100B+ parameter models on fewer GPUs without needing extensive tensor parallelism, drastically cutting down interconnect latency during inference.
| LLM Inference Placement | Configuration | Result |
|---|---|---|
| Standard 192 GB accelerator setup | 2 GPUs with 192 GB each, linked over the interconnect | Requires 2 GPUs to host massive 200B+ parameter models; inter-GPU latency adds overhead |
| AMD Instinct MI350X setup | Single accelerator with 288 GB HBM3e | Large foundation models fit on a single accelerator node, eliminating cross-GPU traffic |
Native Microscaling Formats (MXFP4 and MXFP6)
With CDNA 4, AMD introduced redesigned matrix engine pipelines with hardware support for MXFP4, MXFP6, and FP8 precision formats. Lower precision representation allows data center operators to run larger batch sizes with smaller memory footprints while retaining near-FP16 model accuracy.
Open ROCm 7.0 Software Stack
Hardware power is meaningless without a flexible software ecosystem. The MI350X leverages AMD ROCm 7.0, an open-source software platform providing zero-day out-of-the-box support for leading frameworks like PyTorch, TensorFlow, JAX, and ONNX Runtime. This open ecosystem ensures that developer teams can easily migrate existing AI pipelines without vendor lock-in.
Enterprise teams seeking tailored deployments can evaluate custom Servchip solutions for seamlessly integrating high-density AI clusters.
Deployment Scenarios: How Data Centers Scale the MI350X
The MI350X scales across a wide range of data center footprints, from single-node workstations to full rack-scale clusters. The reference architecture uses AMD Universal Baseboards (UBB) that hold up to 8x MI350X OAM accelerators each, totaling 2.3 TB of HBM3e per board.
| Scale-Out Tier | Configuration | Typical Use Case |
|---|---|---|
| Standalone Workstation Node | Single OAM module connected over PCIe 5.0 x16 | Local LLM fine-tuning and domain-specific dataset generation |
| Universal Baseboard (UBB 2.0) | 8 x MI350X on one board — 2.3 TB total HBM3e VRAM | Heavy model training on dense multi-GPU boards |
| Enterprise Scale-Out — Air-Cooled | Up to 64 MI350X GPUs per rack via 4th-gen Infinity Fabric | Distributed exascale inference and training workloads |
| Enterprise Scale-Out — Liquid-Cooled | Up to 128 MI350X GPUs per system unit | Maximum-density frontier model training |
Standalone workstation nodes give individual teams a single OAM module over PCIe 5.0 x16, ideal for local fine-tuning and domain-specific dataset generation.
For larger clusters, UBB 2.0 modules mount 8x MI350X accelerators on a single board, aggregating 2.3 TB of total HBM3e VRAM for heavy model training. Check out our catalog of enterprise hardware to compare servers and accelerators.
At full scale, 4th-generation Infinity Fabric interconnects allow network engineers to link up to 64 MI350X GPUs in air-cooled rack deployments — and up to 128 GPUs in liquid-cooled configurations — to run distributed exascale workloads.
Global Hardware Deployment and Enterprise Mobility
Deploying cutting-edge hardware infrastructure like the AMD Instinct MI350X across international data centers often involves sending engineering teams abroad for site setup, maintenance, and compliance audits. Servchip coordinates global logistics, sourcing, and delivery so that enterprise teams can deploy MI350X clusters on schedule, wherever they are built.
Selecting the right hardware architecture for your enterprise AI initiatives requires deep expertise in procurement, server compatibility, and thermal management. Read more about Servchip to discover how we assist organizations worldwide in sourcing and deploying state-of-the-art compute hardware.
If you are planning an infrastructure upgrade or need technical guidance on hardware procurement, feel free to reach out directly via our Servchip contact page.
Frequently Asked Questions
What is the primary difference between the MI350X and the MI355X?
While both GPUs share the exact same CDNA 4 architecture and 288 GB HBM3e memory configuration, the MI350X is air-cooled with a 1,000 W TDP, whereas the MI355X is directly liquid-cooled with a 1,400 W TDP for higher clock speeds.
Can the AMD Instinct MI350X be used for PC gaming?
No, the Instinct MI350X is a dedicated data center compute module without display outputs or rasterization hardware, making it strictly intended for AI training, inference, and scientific HPC applications.
How does the AMD Instinct MI350X compare directly to the NVIDIA Blackwell B200?
The MI350X features 288 GB of HBM3e VRAM — 96 GB more than NVIDIA's B200 — allowing larger models to run on fewer GPUs. Operating up to a 1,000 W limit, it uses open-source ROCm 7.0 to eliminate vendor lock-in and cut TCO.
Is it difficult to migrate existing NVIDIA CUDA workloads to the MI350X with ROCm 7.0?
PyTorch and JAX run natively on ROCm 7.0 without code changes. For custom CUDA kernels, AMD's HIPIFY tool automatically converts existing codebases into C++-compatible HIP code.
What are the rack power and infrastructure requirements to deploy an 8-GPU MI350X node?
An 8-GPU MI350X UBB node draws 8 kW for accelerators alone, bringing total chassis power to 10-12 kW with CPUs and cooling systems included. Data centers must deploy high-density PDUs and high-airflow or liquid cooling to safely manage this load.
Final Takeaway
The AMD Instinct MI350X is the strongest direct alternative to NVIDIA in the data center AI segment. With 288 GB of HBM3e memory, 8 TB/s bandwidth, native MXFP4 support and an open ROCm 7.0 software stack, it gives enterprise teams NVIDIA-class performance without vendor lock-in — often at a lower total cost of ownership.
Compared against the NVIDIA B200 and B300, the MI350X wins on raw memory capacity and open-ecosystem flexibility, making it a strong pick for frontier inference and large-batch training. Request an MI350X quote or compare accelerators with our team to size the right configuration for your workload.
Servchip global availability
Enterprise NVIDIA, AMD and Intel hardware is available through Servchip across these regions. Browse local availability, delivery details and region-specific sourcing:
Related Products
Browse chips and systems mentioned in this article
Related Articles
Continue exploring our technical library
ROCm vs CUDA: AMD vs NVIDIA AI Stack Compared (2026)
ROCm vs CUDA in 2026: real benchmarks, cloud pricing, framework compatibility, and a step-by-step migration guide to help you choose the right AI stack.
NVIDIA H100 vs AMD MI300X: Which AI GPU Should You Choose in 2026?
NVIDIA H100 vs AMD MI300X compared on memory, bandwidth, FP16 compute, software ecosystem and price. A neutral spec and use-case comparison to help you choose the right AI accelerator.
AI Chip Market Trends 2026: NVIDIA, AMD, Intel, and Beyond
AI chip market trends 2026: NVIDIA, AMD, and Intel stock moves, semiconductor market forecasts, and what's next for the industry through 2030.